Article
10 minute readSEO Prompt Engineering: Reusable Prompt Templates, Guardrails and QA
SEO prompt engineering that produces work you can check: a seven-part prompt contract, copy-ready templates and a scoring list for every output.
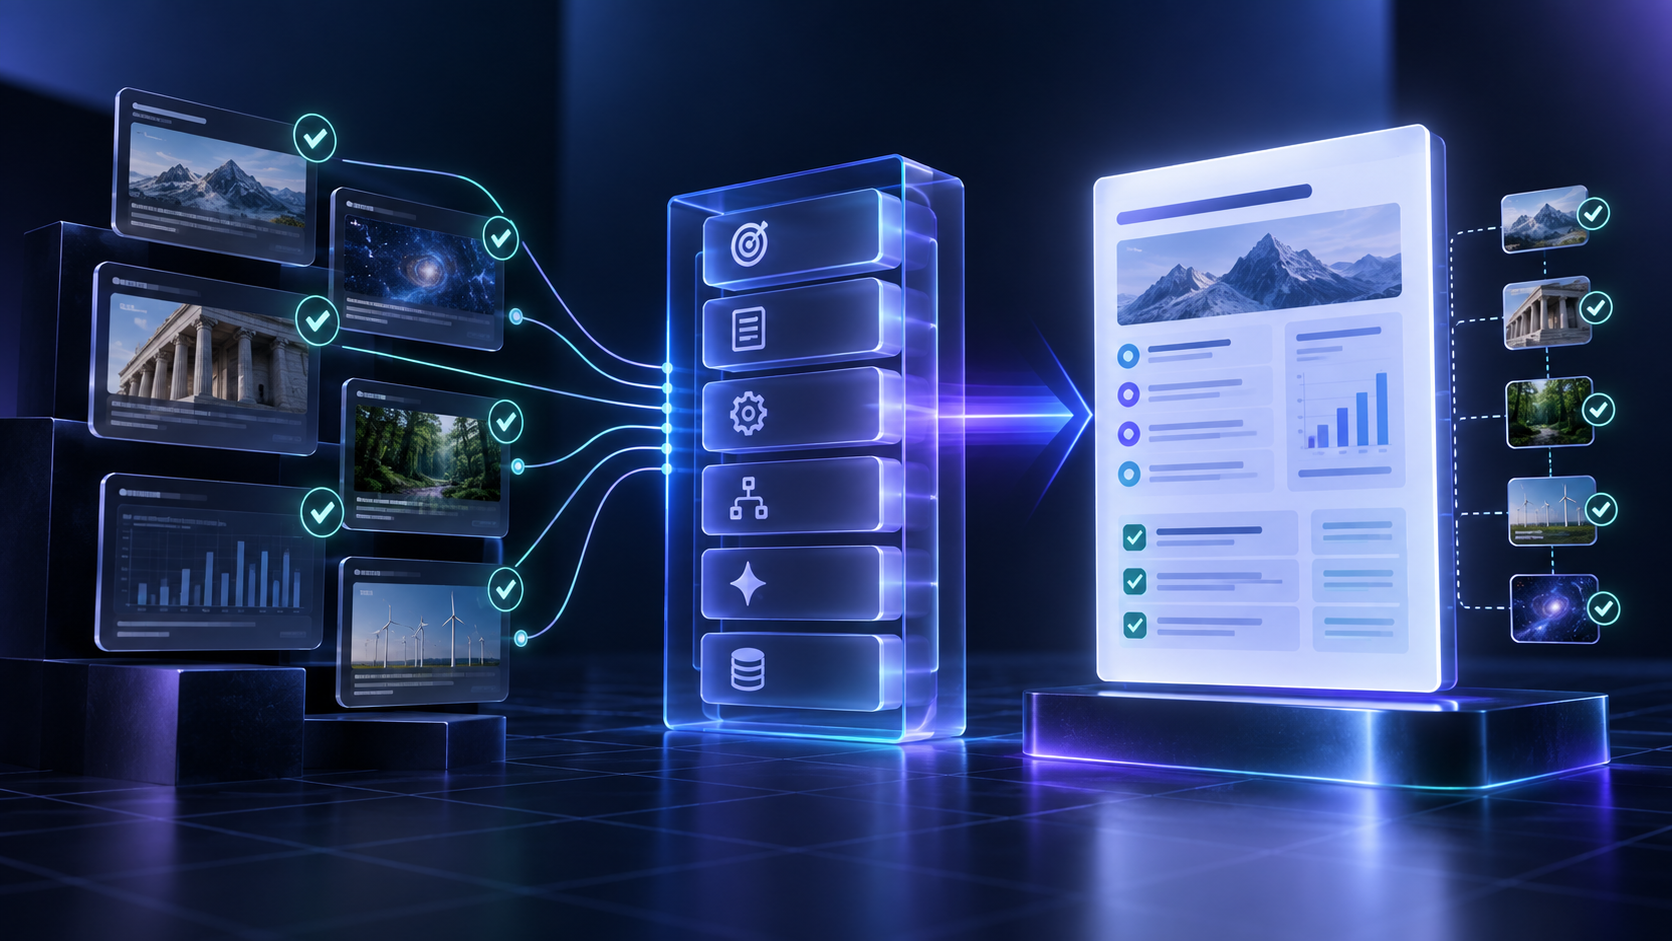
SEO prompt engineering is not about finding a magic sentence. A good SEO prompt is a compact work order: a defined task, known inputs, source boundaries, an output format and a test for acceptance. As a result, the model's output becomes easier to review and less likely to hide unsupported assumptions behind polished prose.
This guide gives you a seven-part prompt contract, three copy-ready templates, a schema that makes uncertainty visible and a checklist to score every output before you use it.
Use a seven-part prompt contract
Every reliable prompt answers the same seven questions. If one is missing, the model fills the gap with guesses, and those guesses look just as confident as facts.
- Role: define the practical perspective, without inventing credentials or experience.
- Goal: state the task and the decision the output should support.
- Audience: name prior knowledge, context, locale and constraints.
- Inputs: provide pages, data, source notes, examples and the date window.
- Rules: set allowed sources, forbidden claims, tone and how to show uncertainty.
- Output: specify fields, order, length range and labels.
- Verification: require claim-to-source mapping, missing-data flags and repeatable checks.
Also keep one principle in mind: the model is not the source. Ask it to work from supplied evidence or to list what needs research, and never treat its confidence or memory as verification.
A reusable SEO prompt template for content briefs
This template turns a topic into a brief you can audit. It forces the model to separate observations from recommendations and to mark gaps as UNKNOWN.
TASK
Create a content brief for [reader task].

AUDIENCE
[Who they are, what they already know, and what they need to decide.]

INPUTS
Use only the supplied Search Console export, page inventory, and source URLs.

RULES
Separate observations from recommendations. Do not invent search volume, rankings, quotes, tests, or product behavior. Mark missing evidence as UNKNOWN.

OUTPUT
1. Intent statement
2. Evidence table: observation | source | date | confidence
3. Proposed outline with purpose for each section
4. Internal-link candidates with destination and reason
5. Risks and verification checklist

ACCEPTANCE TEST
Every factual claim maps to an input. Every recommendation includes a mechanism and a post-publication metric.
Notice the acceptance test at the end. It tells both the model and the reviewer exactly what "done" means.
Extract evidence before drafting
Keep source work apart from prose generation. First, ask for a claim ledger with the claim, source URL, date, exact location, scope and uncertainty.
Then a human opens each source and approves the ledger. Only after that should the model draft from approved claims. This two-pass design makes unsupported leaps much easier to catch.
Prompt for metadata candidates
Titles and descriptions are short, so models tend to overpromise in them. This prompt asks for the evidence behind each promise and the risk of a mismatch.
Generate five title and meta-description pairs for the page below.

For each pair include:
- title
- description
- primary reader promise
- evidence in the page that supports that promise
- risk of mismatch or overstatement

Constraints:
- preserve the page's actual scope
- no guarantee language, fabricated numbers, or keyword lists
- descriptions must be page-specific
- do not assume Google will use the supplied title or description
Choose a pair only after you check its promise against the page. If the page cannot back it up, either improve the page or pick a humbler pair.
Prompt for internal-link suggestions
Supply a list of source passages and candidate destination pages. Then require these fields for each suggestion: source URL, exact passage, destination URL, proposed anchor, reader benefit, relevance score and rejection reason.
The rejection field matters most. A system that must explain why a link might be wrong is easier to audit than one rewarded only for volume.
Make uncertainty visible in the output schema
When the format has a place for doubt, the model uses it. So add fields that record evidence status, source type, date and the final human decision.
For example, a claim marked "needs-source" cannot slip into a draft unnoticed. The table lists fields that work well in practice.
| Field | Purpose | Allowed value example |
|---|---|---|
| evidence_status | Shows whether a claim is ready | verified | needs-source | conflict |
| source_type | Stops weak sources from looking equivalent | primary-doc | standard | paper | secondary |
| as_of_date | Surfaces freshness | 2026-10-03 |
| confidence_reason | Explains the rating | Feature is documented, but rollout varies by account |
| human_decision | Preserves accountability | accept | revise | reject |
Common SEO prompt engineering failures and fixes
Most weak outputs trace back to a handful of prompt mistakes. The fix is usually a clearer instruction, not a longer prompt.
In particular, never ask for current demand without data. That single request causes most invented volume and trend claims.
| Failure | Why it happens | Better instruction |
|---|---|---|
| Generic article | The task names a topic but no reader outcome | Define the user decision and required artifact |
| Invented volume or trends | The model is asked for demand without data | Provide an export or require UNKNOWN |
| Citation-shaped hallucination | URLs are requested without supplied sources | Provide approved sources and require passage-level mapping |
| Keyword stuffing | Success means repeating a phrase | Optimize for task coverage and natural wording |
| Confident outdated advice | No date or platform scope is given | Require current primary documentation and an as-of date |
Score the output before using it
Run every output through the same questions. If the answer to any of them is no, revise the prompt or the inputs before trying again.
- Sources: does every material claim have a source or a visible uncertainty label?
- Task: does the output solve the stated audience task, rather than just include keywords?
- Separation: are observations, inferences, examples and recommendations clearly apart?
- Repeatability: can another reviewer repeat the analysis from the inputs?
- Usefulness: would the page still help readers if search engines did not exist?
- Ownership: has a human checked the rendered page and accepted accountability?
This last question echoes Google's helpful content guidance, which asks whether content is made primarily for people. A prompt can help you get there, but it cannot answer that question for you.
Keep a small prompt library
Store each prompt that passes review with its version, owner, test inputs and known limits. OpenAI's prompt engineering guide similarly recommends clear instructions, examples and testing against evaluations.
Then retest prompts when you change models. A template that worked last quarter can drift, so treat it like any other tool that needs maintenance.
Conclusion
Good SEO prompt engineering produces work products you can check, not prose you have to trust. Use the seven-part contract, supply real inputs, make uncertainty visible and score every output.
Start by adapting the brief template to one live task this week. Then run it three times, compare the outputs and save the version that a colleague can repeat.
Frequently asked questions
Quick answers to the questions readers ask most about this topic.
What is SEO prompt engineering?
It is the practice of writing prompts as clear work orders for SEO tasks: a defined goal, supplied inputs, source rules, an output format and an acceptance test, so the result can be reviewed instead of trusted blindly.
What makes a good SEO prompt?
A specific reader task, the data the model must use, explicit rules against invented numbers or claims, a structured output and a way to mark missing evidence as unknown.
Can ChatGPT or other models give me search volume?
Not reliably. Without a supplied export or a connected data tool, a model may invent volume or trends. Provide real data, or instruct the model to return UNKNOWN.
How do I test whether an SEO prompt works?
Run it on several real inputs, score each output against the same checklist, compare results across runs and keep the prompt only if a reviewer can repeat the analysis from the inputs.
Sources
These references support the platform guidance discussed above. Worked examples are illustrative unless identified as measured results.
Keep reading
Read next
Article 6 min read
AI Translation for SEO: Review Localized Pages Before Launch
AI translation for SEO needs more than fluent wording. Check market fit, meaning, local facts and implementation before a localized page goes live.
Article 6 min read
Data Table Refresh with AI: Update Numbers Without Errors
Run a data table refresh with AI safely: extract with review, calculate with formulas and check only flagged changes before numbers go live.
Article 8 min read
Summarize Research with AI Without Losing Its Caveats
Summarize research with AI while keeping the population, method, limits and the line between correlation and causation intact, using a structured prompt.